
Judgment Zones
Where each part of your organisation stands with AI, what it can do from there — and how you will know whether it worked.
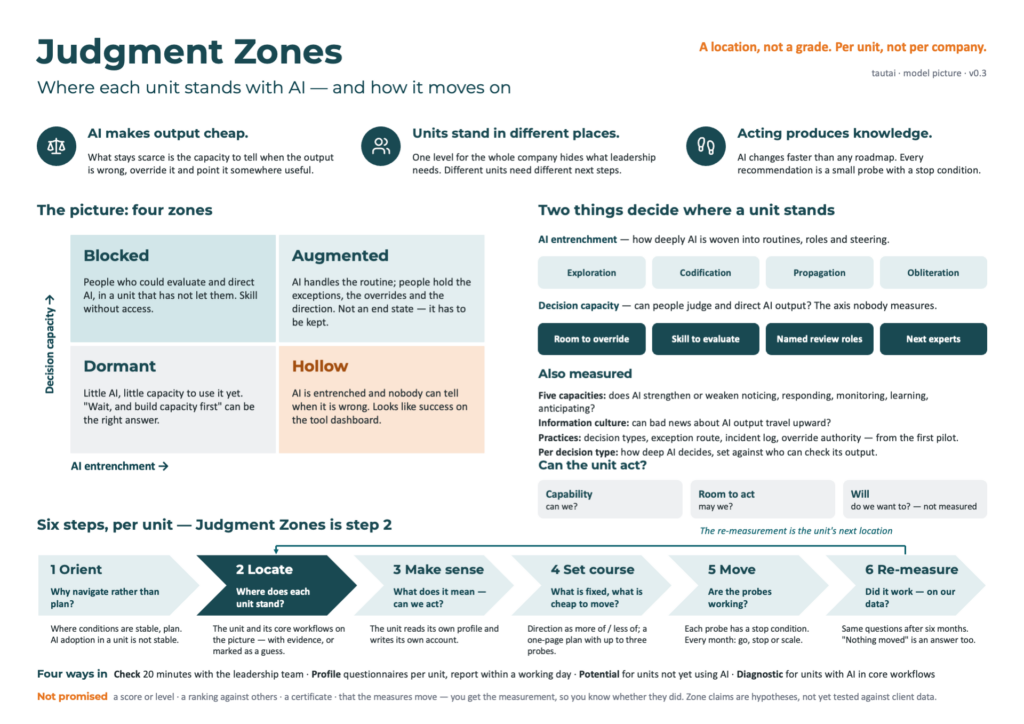
Judgment Zones is an AI capability model. It records a location per unit, not a grade for the company, and it is the second of six steps: for a unit, the location is where the work starts, not where it ends.
Who it is for
A good fit
- Leadership teams in mid-sized organisations that are past the first AI pilots and can no longer say what they actually have
- The units inside them — a department, a business unit, a team that faces its own customers. The steps after the location are taken by the unit’s management team and members, not only by the leadership team
- Internal and external consultants who need a defensible way to talk about AI adoption without selling a five-level ladder
- Managers of a single unit inside a larger group: the model reads at unit and workflow level, so it works without a corporate programme behind it
- Units that have not started at all: the model reads them as a pre-AI baseline rather than as a zero
Not a fit
- Organisations that want a certificate
- Organisations that want a benchmark ranking against their industry
- Organisations that want a roadmap to “level 5”
- Those are available elsewhere.
The problem it addresses
Most organisations have already tried to buy AI capability: pilots that never reached a core workflow, a rollout counted as adoption while decisions are taken as before, a strategy whose assumed models have been replaced since it was written, a policy that arrived before anyone had used a tool or after the first incident.
These are not execution failures. They follow from three habits built for a world that could be planned. Prediction becomes the three-year AI roadmap for a technology that changes quarterly. Best practice becomes the vendor’s case study and the maturity ladder. Linear thinking becomes “more tools, more capability”, when access without the judgment to override is exposure, not capability.
The maturity ladder is what most organisations use to measure progress. Almost every AI maturity model in circulation has the shape inherited from the Capability Maturity Model: five levels, one company-wide result, and the implicit claim that the top level is everyone’s goal. Two systematic reviews of the field find weak theoretical grounding, largely descriptive use, and no longitudinal evidence that moving up a level improves anything. In practice that shape averages away the fact that units of the same company are in different places — and should be. It counts tool rollout as progress. And it measures how much AI is used rather than whether anyone can still tell when the output is wrong.
Where conditions are stable relative to your response cycle — payroll, compliance — planning is right. AI adoption in a unit is not one of those places.
Six steps — Judgment Zones is the second
1 · Orient
Why navigate rather than plan.
2 · Locate
Where each unit stands, per unit and per core workflow: Judgment Zones.
3 · Make sense
The unit reads its own profile: what is happening, what it means, what comes next, and whether it can act.
4 · Set course
The profile placed on a map of what is fixed, what is cheap to move and which way is downhill. A one-page plan of probes, not a roadmap.
5 · Move
Probes with stop conditions; each month, go, stop or scale.
6 · Re-measure
Six months later, the same items. Did the moves work, on your data? “Nothing moved” is an answer.
Units in different zones set different courses at the same time. Step 6 feeds step 2.
Locate: two axes, four zones
AI entrenchment is how deeply AI is woven into a unit’s routines, talent systems and culture. Decision capacity is the unit’s ability to filter, validate, override and direct what AI produces: decision latitude, evaluation skill, judgment-broker roles, and where the next people who can do this come from. The two axes give four zones — Blocked, Augmented, Dormant, Hollow — and one question for a leadership team.
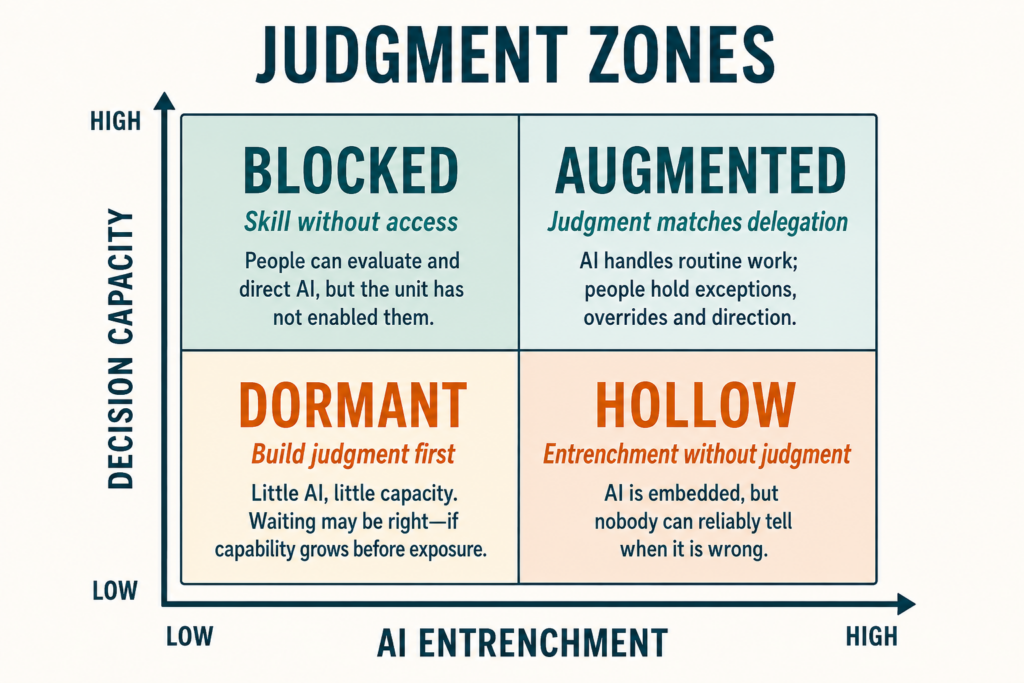
Which of your units is in which zone — and do you know, or are you guessing?
After the location: make sense, set course
The profile is not a report
In a half-day perspective session, the unit’s management team and the members who answered read the profile against their own workflows, not against a benchmark: what is happening here, what it means for our customers, exceptions and people, and what is likely next if nothing is decided. The result is the unit’s own account — where we are, what we want more of and less of. The unit owns it.
Judgment is one element of agency
A unit can act on AI when it has the capability (can we evaluate the output?), the room to act (may we override, and do our decision rights permit a probe?) and the will (do we want to take the exception rather than pass it on?). Decision capacity measures the first two. Will is not measured, by design; the perspective session is where it shows, or shows to be absent.
The map replaces the roadmap
The account and the profile are placed on an estuarine map, an approach imported from Dave Snowden’s work: fixed constraints not worth fighting, scaffolding to build on, quick wins that cost little energy, boundaries that cannot be moved yet. From the map comes one page: a direction stated as more of and less of; up to three probes, each with a stop condition written before it starts; what the unit makes cheaper, such as the override, and what it makes costlier, such as delegating past the judgment available; the monitors; and the date of the re-measurement.
Qualification before consulting
What most units need at this point is people who can read the profile and act on it. Consulting becomes a need only where the map shows something the unit cannot move from inside, and only in some units.
The business case
What a client gets out of it is a decision basis, not a report:
Where to invest next, per unit
Some units need tooling; some need decision latitude; some are right to wait.
Delegation depth matched to decision capacity
You delegate to AI only as deeply as you can evaluate. Where delegation runs ahead of judgment, the model flags it before the exceptions arrive.
Governance from the first pilot
Decision classes, exception routes and an override record exist at exploration stage, sized for a mid-sized firm, and grow into ISO 42001 documentation without a rewrite.
A plan each unit owns
One page per unit instead of one programme for an organisation that is in four different situations.
A trend, not a snapshot
The same items are re-taken every six months and compared against outcome metrics — decision latency, probe-to-scale ratio, governance violations and near-misses, override quality — so the organisation learns whether its own moves worked.
The philosophy
The model applies the core belief of The Tautai Principle to AI: an organisation’s only stability comes from constant adaptation. Three convictions follow.
Judgment is the scarce resource
AI makes output cheap. What stays expensive is the capacity to filter it, validate it, override it and point it somewhere useful.
Location, not grade
Adoption has no known end state, so a ladder cannot say the one thing leadership needs to hear: “you are where you should be.” The model records a position per unit and per core workflow, and never produces a single company score.
Acting produces knowledge
Recommendations are probes with stop conditions, not programmes. What the unit learns by running them, and by measuring again, is the point.
The lineage is explicit: viability rather than fitness from the Viable System Model and The Tautai Principle; agency before access from Education is Broken.
What makes it different
- Decision capacity is measured as a first-class axis — whether the people acting on AI output can tell when it is wrong, are allowed to override it, and where the next people who can do that come from. No published AI maturity model does this.
- The location starts the work. An assessment ends with its result. Here the unit reads its own profile, sets a course on one page and is measured again on the same items.
- One item set behind the measuring tiers. The self-service profile and the two consultant-led tiers read the same items, so they cannot contradict each other, and a unit measured before it adopts anything can be measured again afterwards.
- The model can lose. Each structural claim is published with the observation that would refute it and the point at which we expect data.
- Evidence discipline. Vendor and analyst figures are labelled and never load-bearing. Borrowed instruments cite their source and their validation context.
How to start
Judgment Zones Check
A 20-minute conversation · one picture · no preparation
Which of your units sits in which zone, and do you know or are you guessing?
Judgment Zones Profile
Online · 10–14 minutes for the management team, 5–7 minutes per team member · report within a day
A per-unit profile from your own answers: adaptive potentials, judgment and agency, culture gate, entrenchment location, and up to three probes with stop conditions.
Judgment Zones Potential
For a unit that does not yet use AI · three to four and a half consultant days per unit, plus about a day and a half of engagement overhead
A pre-AI baseline that can be measured again later, whether the stated reason for having no AI is the real one, how deep the unit could delegate given the judgment it has today, and what governance must exist before the first experiment.
Judgment Zones Diagnostic
For a unit that already uses AI in a core workflow · three to five consultant days per unit, plus about a day and a half of engagement overhead
Which viability functions AI has strengthened, bypassed or hollowed out, where delegation exceeds judgment, and a governance record you can hand to an ISO 42001 implementation.
After the location: the perspective session and the map for each unit that wants one. Start with the Check.
None of the four produces a score, a certificate, a benchmark ranking or a roadmap to level five, and “do not start in the next twelve months” is an admissible result.
Where this stands
The model is at version 0.3 and entering pilot use. The zone claims and the capability–outcome links are hypotheses with refuting observations attached; they have not yet been tested against client data. The steps after the location — the perspective session, the map and the one-page plan — are formats designed for the pilot, not validated procedures. We say so here rather than after you have bought something.
Start with the guess you cannot defend
Twenty minutes, one picture, your own units on it. If the room disagrees about where a unit sits, you have found the reason to measure. If it does not, you have lost twenty minutes.
How the model is built, what it measures, who answers it, and what observation would refute it: Method and evidence.